Immutable Data Science with Datomic, Spark and Kafka
summary
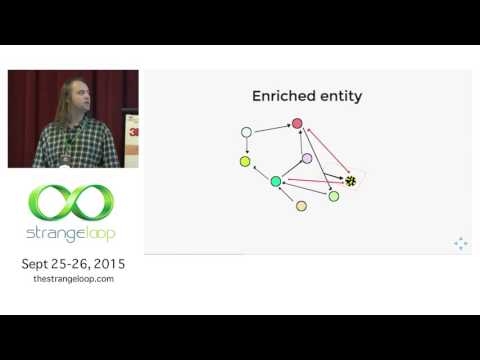
Architecture claims a working pipeline that avoids ETL by combining Datomic, Spark and Kafka so production reads never get copied and models are reproducible. The system uses as-of timestamp snapshots across databases, sharding by entity ID with a mod operation for parallel Spark RDD builds, and stores immutable saved queries that replay exactly. Scoring emits a model output queue containing input output and metadata for traceability, training reuses the same queries into distributed RDDs and keeps persistent materialized views in cluster memory or S3.
AI-written summary · about
chapters (22)
- 0:00Intro
- 1:49Microservices
- 4:08Board
- 5:57How is it stored?
- 6:45How is it queried?
- 9:14How do we get ?
- 10:40Enriched entity
- 13:05Entity from cursor and id
- 13:52Multiple DBS
- 15:34No interference
- 16:45Using it
- 17:08Sample message
- 17:46Sample query
- 18:38Model service
- 19:50Output
- 21:47Scoring time
- 22:05Training time
- 24:45RDDs: our use case
- 26:36Sharding queries
- 28:16Data access
- 29:51Learning curve
- 33:47Testimonials
related talks
 46mThe Datomic Architecture and Data Model
 42mYet & Datomic Immutable Facts Mutated Our Stack
 40mThe power of Datomic database
 40mDatomic: The Most Innovative DB You've Never Heard Of
 51mDatomic
 35mIt's Just Data
 51mImmutable data stores and CORS for safety, flexibility and profit
 37m11 insights after 11 years with the functional database Datomic