Creating correct and capable classifiers

summary
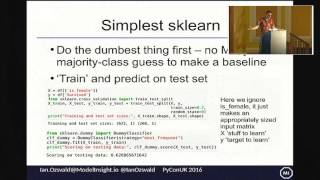
Framework gives concrete checks: start with a dummy classifier baseline (Titanic example ≈0.62), then an untuned random forest reliably improves scores (≈0.83) so performance gains are real not noise. Use pandas_profiling to spot missing or high‑cardinality columns, beware median imputation age=28 that fabricates distributions, inspect confusion matrices and probability histograms, apply permutation importance and ELI5 for per‑prediction explanations, and use YellowBrick and dimensionality reduction to find clustered error modes.
AI-written summary · about
chapters (12)
- 0:00Conference welcome
- 6:06Talk goals and scope
- 7:28Pandas profiling for diagnostics
- 11:20Baseline model with dummy classifiers
- 15:56Imputation pitfalls and visualization
- 17:42Random forests as baseline
- 20:31Visual diagnostics with yellowbrick
- 24:41Feature selection with permutation importance
- 27:30Worst prediction errors analysis
- 30:17Dimensionality reduction for errors
- 34:11Explaining predictions
- 37:18Summary and call to action
related talks
 37mCreating correct and capable classifiers
 27mUsing Machine Learning to solve a classification problem with scikit-learn
 57mHow To Evaluate and Improve Machine Learning Models
 40mMachine Learning Model Evaluation Metrics
 44mHandling predictive uncertainty in Machine Learning
 51mHow to Test Artificial Intelligence and Machine Learning Solutions?
 30mFeature Engineering: An Apprentice’s Guide to the “Dark Art” of Machine Learning
 32mThe Dangers of Mindless Forecasting