Why giving your algorithm ALL THE FEATURES does not always work
summary
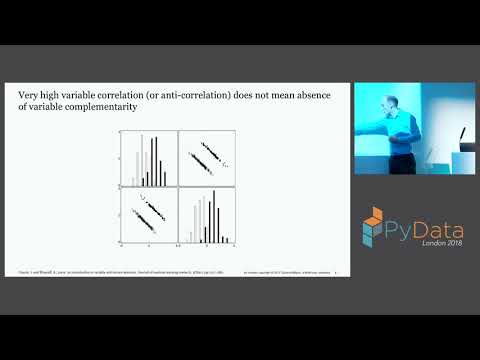
Claim: throwing every variable at a model often worsens performance because of collinearity and weak signals with scarce samples. Shows concrete methods: mutual information filter and greedy approximations, wrapper searches (mlxtend, scikit‑learn) and stability selection that bootstraps a base learner and returns selection probabilities. Points to implementations (skfeature, mifs, stability-selection, skggm) and shows stability selection helping in high‑dimension low‑sample settings while wrappers give best performance at high compute cost and higher overfitting risk.
AI-written summary · about
chapters (8)
- 0:00Introduction
- 3:19Feature selection improves models
- 8:21Feature selection categories
- 9:03Wrapper methods
- 12:00Filter methods and mutual info
- 21:43Embedded methods
- 28:50Choosing the right method
- 31:16Q&A
related talks
 30mMachine Learning Techniques for Class Imbalances & Adversaries
 57mGood Practices for Applied Machine Learning
 30mTraditional & Novel Feature Selection Approaches
 39mData cleaning: when less is more
 46mSolvable Model of Unsupervised Feature Learning
 21mKeynote: Easier Machine Learning Thoughts From Scikit-Learn
 54mOff-the-shelf Algorithmic Stability
 53mRobust Algorithms for Machine Learning