Save your API Keys for someone else
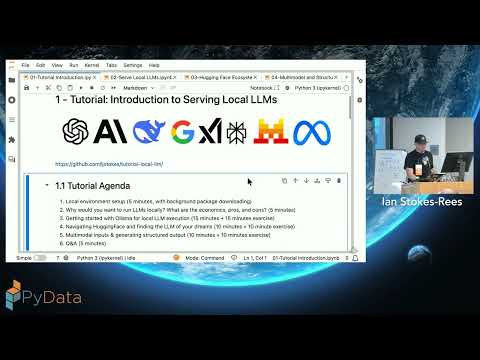
summary
Demonstrates a working, 100% laptop based set of LLMs using Olama plus Hugging Face model downloads and Llama CPP, pulls ~5–6 GB of models over Wi‑Fi, and runs 300M–4B‑parameter models on CPUs with measurable slowdowns. Shows building model variants via few‑shot model file customization to get one‑word sentiment outputs, highlights math failures of base models, and uses LavaFi3 multimodal and Pydantic for guaranteed JSON extraction; overall the examples run locally but need careful hardware and quantization choices.
AI-written summary · about
chapters (12)
- 0:00Introduction
- 9:31Local LLMs and costs
- 23:47First local LLM and queries
- 33:03Chat sessions with models
- 39:24Customizing with system prompts
- 57:06Few-shot training and files
- 1:05:01Model parameters and context
- 1:12:44Hugging Face overview
- 1:22:23Downloading GGUF models
- 1:27:45OpenAI interface and Llama.cpp
- 1:31:33Multimodal inputs and extraction
- 1:34:04Q&A
related talks
 20mSelf-hosting AI LLMs - a beginners guide
 47mLaptop-sized ML for Text, with Open Source
 31mHugging Face ecosystem for Local AI/ ML
 30mLearning to wield large language models
 01h 19mBuilding an LLM on your Laptop to...
 29mRunning Large Language Models on Laptops...
 38mMeta's Roadmap for Full Stack AI
 47mOwn Your LLM: Running Generative and Agentic AI Locally