Building an LLM on your Laptop to...
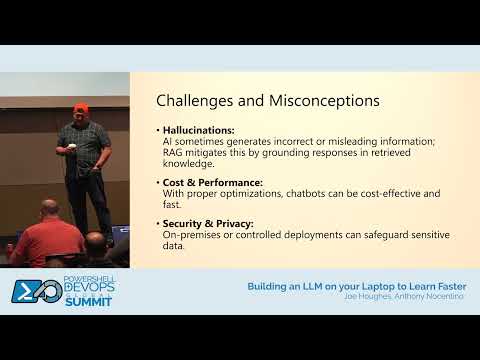
summary
Claims a full local pipeline: Olama and Docker run models on a laptop GPU, use RAG with embeddings stored in SQL and a vector distance query to answer natural language. Tools: local Llama models, unstructured for PDF partitioning, Chroma-like vector store, OpenAI-style embeddings. Demos show a 359‑page PDF parse takes ~26 minutes (65 pages ~6 minutes), and a vector search returns an extra‑large microfiber shirt with cosine distance 0.295. The pipeline works end to end.
AI-written summary · about
chapters (9)
- 0:00Introduction
- 3:28Build local LLM on laptop
- 13:20RAG and embeddings basics
- 23:50Run Ollama locally
- 31:13LLMs via API and PowerShell
- 41:28LLMs with SQL Server and vectors
- 51:17RAG pipeline with Python
- 1:06:03Summarize and query document chunks
- 1:14:58Q&A
related talks
 45mEverything You Need to Know About Running LLMs Locally
 49mLLM—Search Engine Killer?
 27mAI Demystified Unveiling the Intelligence Behind the Machine
 47mOwn Your LLM: Running Generative and Agentic AI Locally
 25mBuilding Advanced LLM Applications with Python and Milvus: A Scalable Vector DB Solution
 18mLLMs and GenAI: A Guide to Building Your Own RAG Model for Document Interaction
 52mAnatomy of an LLM
 46mLLM—Search Engine Killer?