Meaningful Availability
summary
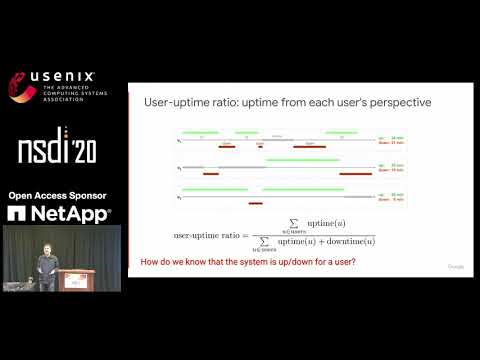
Proposes a concrete metric, windowed user-uptime, that labels each user's intervals as up or down by treating user requests as user probes via request success/fail, then slides many window sizes and plots worst availability per window. Shows synthetic examples where true availability is 66% but success ratio reads 86.4% or is biased by 0.01% hyperactive users, analyzes Gmail-scale traffic (1.5B users), and deploys the metric across G Suite for a year; knees reveal episode durations (e.g., a 15‑minute knee).
AI-written summary · about
chapters (10)
- 0:00Intro
- 2:06Commonly used measure: Success ratio
- 4:21Commonly used measure: uptime ratio
- 5:41Why local outages are the norm
- 6:38User-uptime ratio: uptime from each user's perspective
- 7:55Deriving uptime and downtime per user
- 11:49Visualizing user-uptime across windows
- 13:28User-uptime versus ground truth
- 17:17Does user-uptime match success ratio?
- 17:56Availability and hyper-active users
related talks
 49mWhat It Really Means for Your System to Be Available
 27mBest Practices for Availability
 37mMonitoring the Health of Your App
 48mBuild Trust with Your Users Workshop
 47mUptime == Money: High Availability
 26mQuality and Velocity: A Journey to High Availability
 45mAre Four Nines Enough for Everyone? Understanding Data Center Availability
 46mMeeting Impossible SLAs: How we made our uptime 99.999%