REMIX: Efficient Range Query for LSM-trees
summary
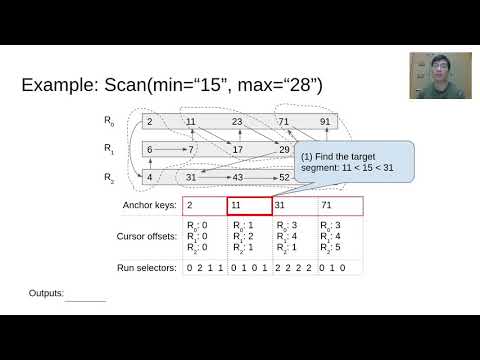
Presents REMIX, a space-efficient KV index that records a global sorted view across multiple LSM table files so range queries locate a start via one binary search on anchor keys and then stream keys without key comparisons. Implements REMIX index inside a new store RemixDB using tiered compaction and single-level partitions. Microbenchmarks show up to 9.3x speedup on 16 files and 2–3x for 50-key scans; YCSB results report up to 2x faster range-heavy workloads and ~30% higher throughput than PebblesDB.
AI-written summary · about
chapters (16)
- 0:00Intro
- 0:24An LSM-Tree
- 1:07Compaction Policies
- 1:54Point Query
- 2:30Range Query---Tiered Compaction
- 2:42Trade-Off
- 3:25Range Query using a Min-Heap
- 4:24Break Down of the Range Query Cost
- 4:57Observation #1: A Stable Sorted View
- 5:25Observation #2: Hardware Trend
- 5:55REMIX Data Structure
- 6:56Example: Scan(min="15", max="28")
- 8:51REMIX Summary
- 9:48Compactions
- 10:10Evaluation
- 11:58Conclusion
related talks
 18mPreview: KV-Stores and Databases
 15mKVIMR: Key-Value Store Aware Data Management Middleware for Interlaced Magnetic...
 21mMatrixKV: Reducing Write Stalls and Write Amplification in LSM-tree Based KV Stores
 15m"Range as a Key" is the Key! Fast and Compact Cloud Block Store Index with RASK
 39mAn Introduction to B-trees and LSM-trees for DEVs and DevOps
 13mClosing the B+-tree vs. LSM-tree Write Amplification Gap on Modern Storage Hardware...
 23mSRFI-167, SRFI-168 and the functional store
 05mExploring Data Deduplication in LSM Tree-based Key-Value Stores (Work-in-Progress Report)