ML Efficiency for Large Models: From Data Efficiency to Faster Transformers
summary
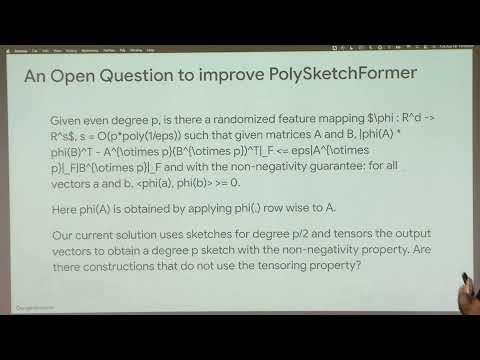
Describes concrete methods and measured wins: sensitivity sampling combines k‑means clustering with importance scores to match full‑data gradients and guides ICML’24 data curation; sequential attention adapts search for feature crosses and block sparsity with OMP/LASSO–like guarantees; HyperAttention uses heavy‑hitter removal plus LSH block diagonalization for near‑linear attention under mild matrix assumptions; PolySketchFormer sketches polynomial attention (degree ~6–8) to get provable linear time, constant‑time next‑token generation and 2–4× speedups at 32‑token contexts.
AI-written summary · about
chapters (9)
- 0:00Introduction
- 1:50Graph mining to ML efficiency
- 3:38Generative AI challenges
- 6:51Subset selection for efficiency
- 17:49Sensitivity sampling for LLM data
- 22:31Sequential-attention feature selection
- 26:04Fast transformers with linear attention
- 32:28Future directions in ML research
- 34:39Q&A
related talks
 37mUnstructured Sparsity Meets Tensor Cores: Lessons from Sparse Attention and MoE
 34mTalk by Mahdi Soltanolkotabi (University of Southern California)
 26mRethinking the Transformer: Toward Native Multimodal Architectures
 01h 25mPaper Discussion: Attention is all you need
 13mInside Multimodal Models
 19mOptimizations and abstractions for sparse machine learning
 40mPanel discussion "NLP"
 49mThe Building Blocks of Today’s and Tomorrow’s Language Models