Lightning Talks
summary
New result: a polynomial‑time algorithm for high‑dimensional mean estimation that matches Gaussian sample‑error up to a 1+o(1) factor in constant dimension, proven via a semidefinite program. It recenters using a preliminary mean, then optimizes an SDP over per‑sample weights so the post‑trimming covariance is bounded in every direction, choosing the scale so the total weight removed is throw out a third log Delta samples. Proof uses KKT duality to show the weights arise from a quadratic form; analysis currently handles constant d though numerics suggest a stronger regime.
AI-written summary · about
chapters (11)
- 0:00Lightning talks welcome
- 10:05Mean estimation in high dimensions
- 23:21Hypothesis selection data structures
- 32:58Correlation clustering beyond pivot
- 42:10Sampling motifs in temporal networks
- 52:29Low degree testing over reals
- 1:00:38Fully dynamic matching with two-minus-root approximation
- 1:11:39Robust graph communities
- 1:21:20Quantile estimation with local DP
- 1:30:11Errors in cumulative knowledge
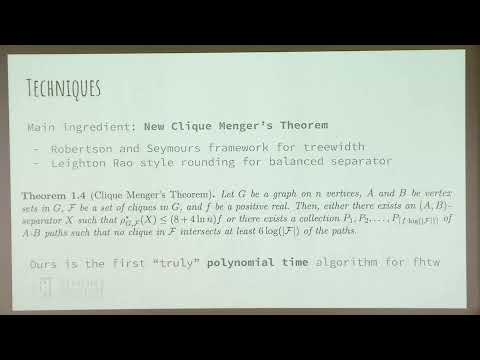
- 1:38:23Fractional hyper tree decompositions