Unicode: From First Principles to Practical Implementation

summary
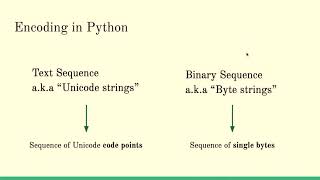
Explains the concrete claim that Unicode is a numbered universal character set (about 1.1 million code points across 17 planes), contrasts encodings like UTF‑8 vs UTF‑16, demonstrates live coding in Python live coding (showing grapheme vs character, skin‑tone emoji as multiple code points), shows CLDR/ICU driving locale formats and Babel for date/number formatting, and runs an automated workflow using LLM auto‑translation via Lokalise to push/pull translation files so developers see where corruption, DB length limits, and practical fixes actually happen.
AI-written summary · about
chapters (13)
- 0:00Introduction
- 6:22Why Unicode was invented
- 11:53Apple and encoding issues
- 14:00Unicode architecture
- 20:23Unicode planes and assignments
- 27:08Unicode Character Database
- 36:15Graphimes and corruption
- 44:29Graphimes pitfalls
- 48:05Locales in systems
- 56:11Translation management
- 1:04:52Localizing data formats
- 1:17:34CLDR and ICU libraries
- 1:20:27Q&A