Trapped in codepoints no more! I’m freeing Chinese characters
summary
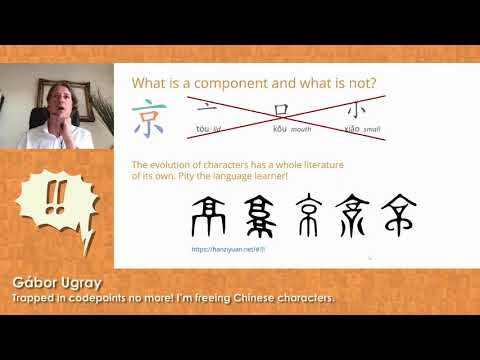
Project builds a machine-readable dataset of Chinese characters that records components, stroke order and function rather than single Unicode code points, and it reaches 20% of 9,000 characters after two years of work. Tools include a Berg bench annotator, provenance from printed sources and the make me a honza stroke extractor, interactive visualizations with D3.js, an iPhone prototype with handwriting recognition, and data that promotes SVG shapes as first-order citizens into a structured JSON output per character.
AI-written summary · about
chapters (10)
- 0:00Introduction
- 0:36Chinese writing crash course
- 3:30Unicode representation challenges
- 5:16Font system limitations
- 6:21Components dataset creation
- 7:03Berg Bench tool
- 9:13Structured data outcome
- 9:57Network Explorer demo
- 11:00iPhone handwriting app
- 12:25Future plans and collaboration
related talks
 47mData, Design, Code
 42mData, Design, Code with Shirley Wu
 37mSupporting Data Journalism through Compilers for Visual Inputs
 41mData, Design, Code
 43mData Sketches | A year of exotic data visualizations
 47mData Sketches: a year of exotic data visualizations
 21mDataInk: Direct and Creative Data-Oriented Drawing
 30mdata sketch|es: a year of exotic data visualizations