The Linear Algebra of Deep Learning

summary
Argues that deep nets reduce to linear algebra and demonstrates two concrete speedups: using randomized SVD to compress large matrices by choosing target rank k and oversample p=k for a 2k approximation with error bounded by roughly the (k+1)th singular value (example: 1000×1000 satellite image rank 844 where k≈80 gives usable reconstructions), and turning convolutions into matrix multiplies via im2col and blocked GEMM with tiling/partitioning so GPUs/CPUs stay busy. Shows numpy SVD ~468 ms vs TensorFlow/randomized ≈13.8 ms and points to Intel MKL and cuBLAS implementations.
AI-written summary · about
chapters (12)
- 0:00Intro
- 0:25ABOUT ME
- 4:07MATRIX MULTIPLICATION FUNDAMENTAL TASK
- 5:09TOP 10 ALGORITHMS OF THE 201 CENTURY.
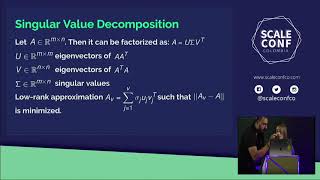
- 6:43SINGULAR VALUE DECOMPOSITION
- 15:57RANDOMIZED SVD: Halko-Martinsson-Tropp
- 23:35SVD NAÏVE BENCHMARK r=15 np. linalg.svd 180 loops, best of 3: 468 ms per loop
- 26:45GEMM: COMPUTATION TIME
- 27:26GEMM: ARITHMETIC INTENSITY
- 28:46GEMM: CONVOLUTIONAL LAYERS
- 36:22GEMM: PARTITIONING
- 40:18REFERENCES
related talks
 32mA Primer (or Refresher) On Linear Algebra for Data Science
 34mThe Linear Algebra of Deep Learning
 01h 31mPast, Present and Future of Randomized Numerical Linear Algebra II
 01h 27mPast, Present and Future of Randomized Numerical Linear Algebra I
 32mRandomized Numerical Linear Algebra: Overview
 41mUnveiling the simple math that powers AI
 01h 02mTheory and Big Data
 55mA Tour of Deep Learning With C++