Estimation and Trust-Driven Development

summary
Estimation treats story complexity as the reliable signal and velocity as the calibratable one: break work into Fibonacci-sized stories, assign points measure complexity, run a couple of iterations to learn throughput, then translate a point to hours (example 5–7 hours/point) and present a low/high range (example project 120–145 points → ~$150k–$250k, with a likely band like $160k–$180k). Avoid false precision, state assumptions, and surface ranges to build trust.
AI-written summary · about
chapters (13)
- 0:00Start
- 0:46better?
- 1:08Avoid false precision
- 1:49What goes into the amount of calendar time a feature takes?
- 2:01Complexity of the task Skill of the developer Time on task
- 2:27We are bad at estimating time on task
- 7:05Decomposing the problem into similar size chunks helps
- 7:56Requires Time
- 8:21How do I estimate at the beginning of a project?
- 8:36Fake it
- 9:12Realize that your output is a range
- 10:59At the beginning (and only at the begining) You can range estimate stories
- 11:57load factor (5 - 7 hours per point)
related talks
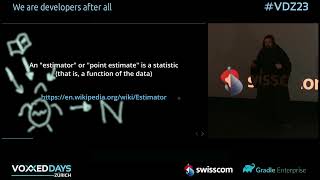 48mRespect estimates
 40mEstimations: from guessing to weighing in grams
 40mStory Points considered Harmful- a psychologist's thoughts on estimation
 20mSticking the Landing
 01h 01mLies Developers Tell Themselves
 51mRespect estimates
 07mThe art of precision: strategies and challenges of estimations...
 07mLightning Talks