Sampling Big Ideas in Sublinear Algorithms

summary
Presents concrete algorithms: use order-statistics scoring (exponential or priority hashes) to get PPSWOR without knowing total weight, implementable in streaming/distributed settings and computable near-linearly for graph problems; attach sticky per-key randomness to coordinate samples across instances, yielding much smaller multi-objective unions and high agreement for private-ML teacher ensembles; core claims are optimal inverse-probability error bounds hold (covariances nonpositive), sliding-window and all-distance sketches need about k log n storage per object, and graph all-distance sketches run in near-linear time and work in practice.
AI-written summary · about
chapters (16)
- 0:00Sampling in sublinear algorithms
- 3:33Composable data structures
- 5:37Linear queries from samples
- 9:16Order statistics sampling
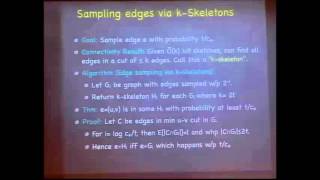
- 15:39Graph sketches near-linear
- 18:34Linear queries exponential scores
- 24:49Adapting samples to weights
- 26:17Sticky per-key randomness
- 32:55Multi-objective samples
- 37:53Monotone multi-objective samples
- 40:28All-distance graph sketches
- 43:27Unaggregated data sampling
- 53:34Frequency functions sampling
- 58:07Heavy hitter transforms
- 1:00:16Summary applications
- 1:01:05Q&A
related talks
 01h 24mStreaming, Sketching and Sufficient Statistics I
 01h 04mNew Algorithms for Heavy Hitters in Data Streams
 01h 26mStreaming, Sketching and Sufficient Statistics II
 43mSub-Quadratic Recovery of Correlated Pairs
 01h 13mSketching High-Dimensional Data
 48mHomomorphic Sketches: Shrinking Big Data without Sacrificing Structure
 55mTheory of Data Streams
 24mSketching Algorithms: Making Sense of Big Data in a Single Stroke