Beyond Shuffling: Scaling Apache Spark

summary
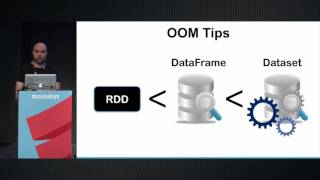
Shows concrete fixes and measurements: use reduceByKey or aggregateByKey instead of groupByKey to get map‑side reduction (example: shuffle read drops from ~48 KB to ~11 KB), prefer checkpoint then persist on noisy shared clusters to avoid recompute, avoid turning partition iterators into lists inside mapPartitions, and reuse shuffle files but trigger worker GC to clean them. Recommends DataFrames/Datasets for compact serialization and pushdowns, warns of lineage explosion for iterative algorithms and suggests an RDD round‑trip as a practical workaround; default 200 partitions often needs tuning.
AI-written summary · about
chapters (17)
- 0:00Intro
- 2:02What is going to be covered
- 3:58The different pieces of Spark
- 10:15What is key skew and why do we care?
- 16:06Well there is a bit of magic in the shume....
- 18:36Iterator tortor transformations
- 22:21Why is Spark SQL good for those things?
- 23:54How much faster can it be?
- 25:42How to avoid lineage explosions
- 26:32Introducing Datasets
- 28:50And functional style maps
- 29:33Switching gears: Valdating Spark jobs
- 34:22Using an accumulator for validation
- 35:56Validating records read matches our expectations
- 37:22Additional Spark Testing Resources
- 37:36Additional Spark Resources
- 39:43Spark Videos
related talks
 40mScaling with Apache Spark (or a lesson in unintended consequences)
 41mOptimising Apache Spark and SQL for Improved Performance
 15mOptimizing Query Performance in Big Data Systems
 50mChallenges that everyone struggles while productionizing Apache Spark workloads
 40mProblem Solving Recipes Learned from Supporting Spark
 28mAn Apache Spark query's journey through the stack
 44mProcessing large data with Apache Spark
 53mTips and tricks for robust big data applications