Anyone can Build Great Deep Learning Applications - Deep Numpy

summary
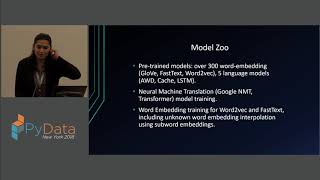
Claims that existing NumPy code runs unchanged but on GPU via Deep Numpy, with MXNet NDArray compatibility and multi‑GPU parallelism. Demonstrates transfer learning through model zoos (GluonCV, GluonNLP), architecture search (NAS and ENAS with weight sharing), and hyperparameter search using Bayesian optimization and reinforcement learning. Shows a real optimization cutting training from two days to under an hour and cites a projected $22M annual training saving. Releases and APIs named: MXNet, GluonCV, AutoGluon.
AI-written summary · about
chapters (8)
- 0:00Democratizing AI with Deep Learning
- 6:32Deep Numpy motivation and challenges
- 8:40Deep Numpy demo and performance
- 11:14Auto Gluon ML toolkit overview
- 16:14Bayesian optimization in Auto Gluon
- 23:58Reinforcement learning and NAS in Auto Gluon
- 27:41Deep Numpy future developments
- 29:06Q&A
related talks
 29mAccelerate NumPy Data Science Workloads and Deep Learning Applications
 39mAccelerate large-scale machine learning with NP on MXNet
 41mReally Deep Neural Networks with PyTorch
 38mThe new kid on the block: deep learning with GluonNLP
 28mDeveloper Essentials for the New Era of AI
 01h 22mWhat's inside the box? Building a deep learning framework from scratch.
 23mBest Practices for Building Production-Grade Deep Learning Systems
 30mApache MXNet 2.0: Towards Synergistic ML and DL with Standardization