Testing and Validating MLMs
summary
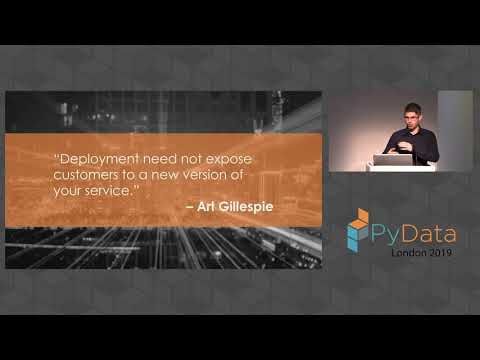
Reproducibility between research and production is the stated hard claim and the recommended guardrail: reproduce past predictions, then run a shadow deployment that records live inputs and outputs without affecting customers, compare distributions with KS test and chi square skew tests, watch feature-level breaks and missing upstream data, use canary release for staged rollouts, instrument with feature flags or load‑balancer branching, and tie artifacts to data science version control DBC so deployments are deterministic and monitoring catches performance drift.
AI-written summary · about
chapters (7)
- 0:00ML testing challenges
- 3:20ML production readiness
- 8:54Shadow vs canary releases
- 12:26Shadow deployment analysis
- 16:38ML pipeline reproducibility
- 25:08Model release steps
- 26:47Q&A
related talks
 30mHow to Properly Test ML Models & Data
 30mFrom Black Box to a Known Quantity: How to Build Predictable, Reliable ML-based
 32mReproducibility and versioning of ML systems
 21mTesting in Production
 32mI Test In Production
 22mTesting in Production
 26mTesting a Data Science Model
 29mReproducibility in ML Systems: A Netflix Original