End to End Machine learning pipelines for Python driven organizations
summary
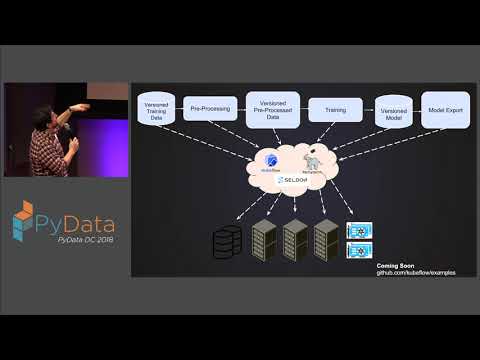
Claim: pachyderm gives data provenance by assigning commit IDs to every dataset change so every model input and output is traceable. Tools actually used are docker containers on kubernetes, with pipeline specs, cron/webhook triggers, row-splitting for large tables, and integrations like Seldon and Kubeflow. Demo shows object-detection pipeline that auto-runs on repo commits, rebuilds models on data edits, and exposes deletion/reproducibility behavior (full GDPR-style history purges are noted as work in progress).
AI-written summary · about
chapters (8)
- 0:00ML pipeline introduction
- 3:093 ML pipeline challenges
- 7:58Reproducible ML workflows
- 15:00Data provenance and GDPR
- 19:20Pachyderm live demo
- 26:32Automating pipelines
- 33:20Pachyderm resources
- 38:35Q&A
related talks
 33mCompliant Data Management and Machine Learning on Kubernetes
 30mRealizing End to End Reproducible Machine Learning on Kubernetes
 19mModern Data Science in a Cloud Native World
 20mBetter Care and Feeding of Machine Learning Models
 01h 25mBest practices and solution design using data versioning for machine learning
 57mDevOps for Machine Learning
 35mOrganizing data engineering around Kubeflow
 59mDevOps for Machine Learning Projects