Best Practices for Hyperparameter Optimization

summary
A simple betting model beat the house using SigOpt after hyperparameter tuning, turning a losing approach into a money-making one and demonstrating real-world gains. Advice: optimize pipeline including feature extraction and model architecture together to capture interactions, use k‑fold cross‑validation to avoid overfitting, and prefer Bayesian optimization for expensive evaluations. Grid search explodes (5 params × 10 values → 100,000 evaluations) and random search ignores past results; Bayesian balances exploration and exploitation for minutes‑to‑hours training runs.
AI-written summary · about
chapters (14)
- 0:00Intro
- 0:33Example: Beating Vegas
- 3:52Optimize all Parameters at Once
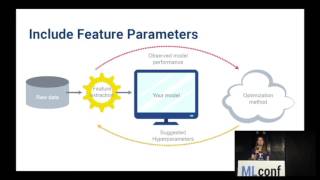
- 5:03Include Feature Parameters
- 8:40Composite Metric Example: Lifetime Value
- 9:11Choose Multiple Metrics
- 11:12Split Data into k Subsamples
- 11:23Evaluate Performance on Subsample 1
- 11:35Report An Observation
- 11:48Repeat for New Hyperparameters
- 13:49Alternatives to Hand Tuning
- 14:05No Grid Search
- 15:04No Random Search
- 16:36Alternatives to Bayesian Optimization
related talks
 41mOptimizing Machine Learning Models
 18mAlexandra Johnson, Software Engineer, SigOpt, NYC 2017
 24mUsing Bayesian Optimization to Tune Machine Learning Models
 26mAddressing Some of Challenges When Optimizing Long-to-Train-Models
 38mA Guide to Modern Hyperparameters Turning Algorithms
 34mBayesian Optimization and it's application to Neural Networks
 25mHyperparameter Tuning and Visualization in Deep Learning
 26mModel Selection with Python: An Introduction to Hyper Parameter Tuning