Crunching Big Data with Julia
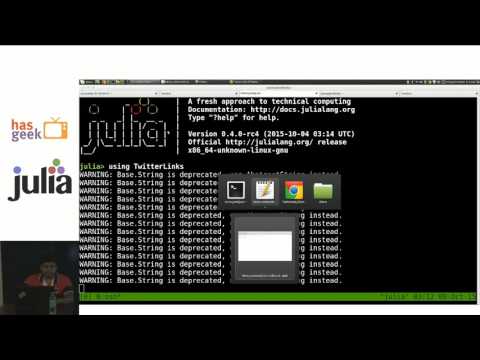
summary
A demonstration of a big-data workflow built with Elly.jl that provides a pure-Julia HDFS and YARN client without libhdfs. Shows a ClusterManager-style API (addprocs, @parallel, spawn, pmap) to run Julia parallel constructs on a YARN cluster, plus lower-level YARN application APIs and a Julia IO interface for HDFS files, and processes concrete datasets end-to-end so tools and results are visible.
AI-written summary · about
related talks
 45mSolving Real & Big (Data) Problems Using Hadoop
 51mBIG DATA STORAGE & PROCESSING: Introduction to Hadoop and Its Ecosystem
 59mHadoop Essentials for the SQL Server Professional
 55mSolving Classical Data Analytic Task by Using Modern Distributed Databases
 45mFrom Big Data to Big Information
 44mDeveloping for Big Data at the Intersection of Containerization and Infrastructure as Code
 47mWhat's Ahead for Big Data?
 01h 48mBig Data made easy with a Spark (3.0)