Cluster Serving: Distributed Model Inference using Apache Flink in Analytics Zoo
summary
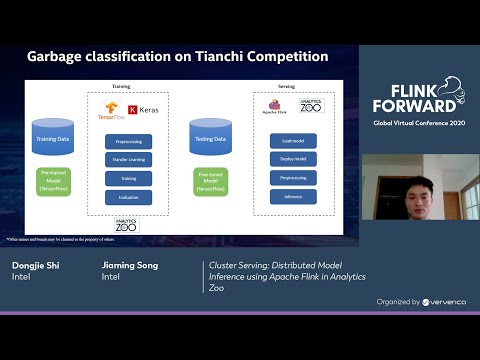
Cluster Serving runs on Apache Flink via Analytics Zoo and provides automatic distributed serving for TensorFlow, PyTorch, Caffe, BigDL and OpenVINO models with Docker/Kubernetes deployment. It exposes pub/sub and REST APIs, auto-loads model types, and uses a Flink Blink continuous streaming pipeline (Spark streaming also supported) for low latency and cluster-wide scale-out; multi‑thread optimizations reduce bottlenecks. Real deployments move large-image medical inference from ~1–2 hours to minutes and scale garbage‑classification inference across executors successfully.
AI-written summary · about
chapters (13)
- 0:00Intro
- 0:32Outline
- 1:07Big Data & Model Performance
- 2:06Real-World ML/DL Applications Are Complex Data Analytics Pipelines
- 3:18Integrated Big Data Analytics and Al Seamless Scaling from Laptop to Distributed Big Data
- 5:13Analytics Zoo Unified Data Analytics and Al Platform
- 7:16Example of Classical Web Serving
- 8:06Distributed Model Serving
- 8:50Architecture of Main Version of Cluster Serving
- 10:05Advantages of Analytics Zoo Cluster Serving
- 12:52Cluster Serving Workflow Overview
- 15:29API Introductions - Pub-sub
- 16:13Garbage classification on Tianchi Competition
related talks
 18mCluster Serving: Distributed Model Inference using Big Data Streaming
 21mIntroducing FlinkML
 21mReal-time Stream Analytics and Scoring Using Apache Flink, Druid & Cassandra
 35mAdvanced Model Inferencing Leveraging KNative, Istio & Kubeflow Serving
 29mBuilding Resilient AI Platforms: Financial Fraud Detection
 36mIntroducing Kubeflow (w. Special Guests Tensorflow and Apache Spark)
 40mHow to leverage the Apache Kafka Ecosystem to productionize Machine Learning
 40mScalable machine-learned model serving