Apache Flink in the Cloud-native Era

summary
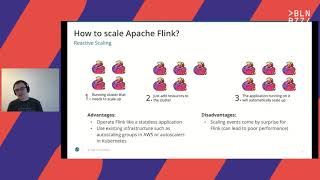
Apache Flink is moving toward cloud-native operations with concrete features: buffer debloating reduces in-flight data so checkpoints become snappier, aiming for predictable 2–5 second checkpoint cadence; generalized log-based incremental checkpoints decouple checkpointing from heavy compactions to avoid long snapshot delays; reactive scaling mode lets jobs scale when Kubernetes adds or removes pods; a demo shows persistent volumes for failover recovery cutting state restore from ~10 seconds to under 1 second.
AI-written summary · about
chapters (8)
- 0:00Apache Flink's stats in the ASF 2020
- 3:14Apache Flink in the Cloud-native Era
- 11:25Four initiatives that change Flink's Cloud-native Nature
- 11:38Better Operations APIs
- 12:41Predictable Fast Checkpoint Times
- 19:08Elasticity
- 25:41Faster Failover
- 29:30Demo - Persistent Volumes for Failover Recovery
related talks
 42mApache Flink deep-dive #bbuzz
 31mRethinking of fault tolerance in Flink: what lies ahead?
 28mA look at Flink’s internal data structures & algorithms for efficient checkpointing
 37mKeynote | Flink Ahead: What Comes After Unified Batch & Streaming?
 35mApache Flink 2.0: Unified Enterprise Data Processing System and Beyond
 20mAutoscaling Apache Flink Applications
 34mBeaming Flink to the Cloud @ Netflix
 26mRunning Apache Flink on AWS