FPGA-Accelerated Compactions for LSM based Key-Value Store
summary
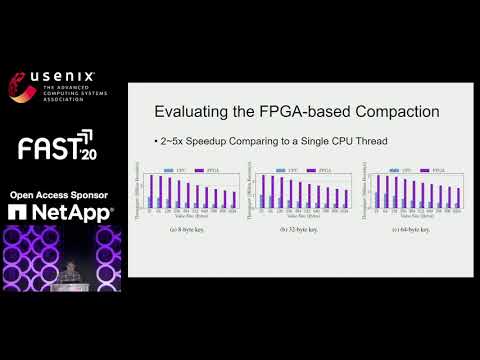
Offloads LSM compactions to FPGA co‑processors integrated with X-Engine, implementing pipelined decoder–merger–encoder compaction units over PCIe and running up to eight CUs per board. Measures show 2–5× compaction throughput, up to 23% higher database throughput and 31.7% better transactions‑per‑watt versus a tuned CPU baseline, with only ~0.03% of tasks falling back to CPU because of a 6KB value size limit; current bitstream uses roughly half the FPGA resources.
AI-written summary · about
chapters (11)
- 0:00Start
- 1:41LSM-based Key-Value Store
- 2:49The Performance Fatigue Problem
- 6:56Integrating FPGA as a co-processor
- 12:14Experimental Setup
- 12:30Evaluating the FPGA-based Compaction
- 13:29Compaction Unit Resource Consumption
- 16:27Macro-benchmark
- 17:32Evaluation Takeaways
- 17:58Conclusion
- 19:28The Value of Adding an FPGA
related talks
 17mHardware Accelerated Big Data Processing
 28mAchieving 10Gbps Line-rate Key-value Stores with FPGAs
 06mAchieve predictable performance
 22mPinK: High-speed In-storage Key-value Store with Bounded Tails
 18mPreview: KV-Stores and Databases
 20mPacman: An Efficient Compaction Approach for Log-Structured Key-Value Store...
 27mPreview: Storage
 23mEnabling SQL to FPGA Using HLS for Filtering/Stream Data Transformations