Real time Platform for Second Look Business Use Case Using Spark & Kafka
summary
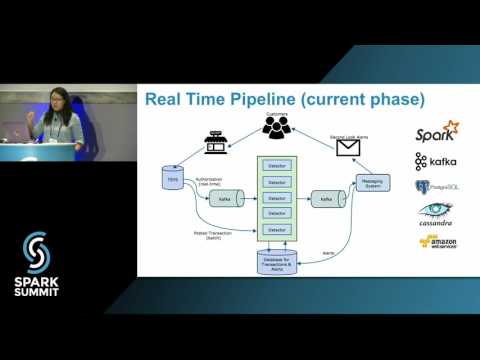
Capital One builds a real‑time pipeline for Second Look using Spark and Kafka to move from Hadoop MapReduce + MongoDB + Luigi to a low‑latency AWS stack (Postgres, Cassandra) that turns authorizations into alerts before customers put cards away. The system auto‑enrolls credit card holders and sends tens of thousands of alerts per day, handles both real‑time and large batch posted loads, enforces dedupe at the database and uses Kafka offsets (Zookeeper) to achieve at‑least‑once processing with zero‑loss goals.
AI-written summary · about
chapters (11)
- 0:00Introduction to Second Look
- 1:05Problem with credit card statements
- 4:45What is Second Look feature
- 7:37Initial pipeline with Hadoop
- 8:41Need for real-time alerts
- 9:25Realtime pipeline architecture
- 11:57Microservice-based design
- 13:24Handling data duplication
- 14:27Checkpointing for zero loss
- 16:14User feedback and results
- 18:25Q&A session
related talks
 57mEmergence of Real-Time Analytics: Real-time Analysis of...
 08mReal-Time Data Systems: Speed, Scale, and Resilience
 38mRealtime Data Activation - Analytics, Intelligence & Decision Making
 21mModeling Financial Data In Cassandra To Serve Real Time And Batch Workloads
 01h 00mPutting Apache Kafka to Use
 49mEnriching Kafka Applications With Real-time Contextual Data
 30mFive Challenges in Real-time Stream Processing and Five Solutions
 35mReal Time Marketing with Kafka, Storm, Cassandra & Spark #bbuzz