Parallel computing in Python: Current state and recent advances
summary
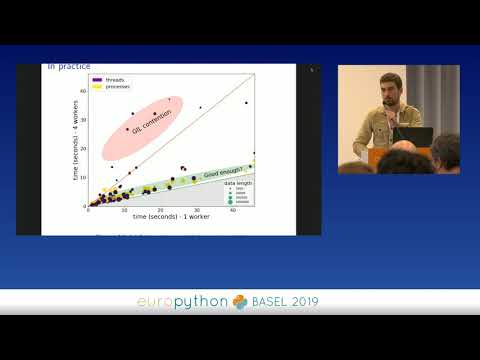
Shows concrete fixes and numbers: multiprocessing (process pools) beats threads because of the GIL, four-worker benchmarks approach ideal speedups for many scikit-learn estimators but threads produce outliers. Introduces loky + joblib for robust interactive pools, persistent memoization on disk, and optimized NumPy transfers. Explains serialization: cloudpickle C-extension is ~30× faster than pure Python, and pickle protocol 5 adds zero-copy buffer support and shared-memory facilitation (Python 3.8+) that tools like dask, ray and pyspark adopt to cut memory copies and latency.
AI-written summary · about
chapters (8)
- 0:00Introduction
- 1:05Why parallel computing matters
- 3:33Thread vs process parallelism
- 8:28Process-based parallelism limits
- 9:10Standard library solutions
- 13:26Third-party libraries overview
- 17:25Recent advances in Python
- 27:54Key takeaways and conclusion
related talks
 30mPython Serialization and the Hallows of Parallel Computing
 34mUnderstanding of distributed processing in Python
 35mWriting robust, readable, and maintainable concurrent programs in Python
 30mParallelization of code in Python for beginners
 41mParallelism in Numerical Python Libraries
 30mSpeed Up Your Data Processing
 31mPython Multithreading and Multiprocessing: Concurrency and Parallelism
 10mRedlining Your CPU for Fun and Profit: Threading and Multiprocessing in Python