The Modern Data Stack

summary
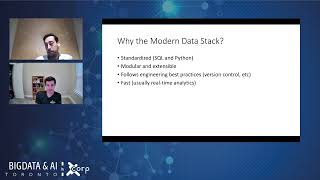
Claim: the modern data stack replaces Hadoop/Spark ops with cloud services so analysts become analytics engineers. Demo builds a working pipeline: MongoDB + MailChimp → FiveTran ingestion to BigQuery (233 rows in sample), transformations in DBT for transformations (staging → marts as views/tables), scheduled runs hourly, Tableau report layer. Notes include CDC limits with read-replicas leading to FiveTran Teleport sync and hashed PII joins via hashed PII joins.
AI-written summary · about
chapters (10)
- 0:00Introduction
- 7:57What is the stack
- 13:01Cloud data warehouses
- 20:27Data storage history
- 35:55Stack architecture
- 41:18DBT transformation
- 52:31Stack advantages
- 1:00:10Q&A
- 1:11:10Demo of tools
- 1:33:27Closing
related talks
 01h 28mA Guide to the Modern Data Stack
 50mMasterclass: Building a data stack in 2021
 41mModern Data Architectures – What They Are and How to Implement?
 25mPerfecting Our Modern Data Stack Recipe: What We Learned On The Journey At Huel
 19mDemystifying Modern Data Pipeline Architecture
 45mModern Data Architecture
 29mNavigating the Modern Data Stack with Open Source Headless BI
 46mA Brief History of Big Data