Observability - the practical approach
summary
Snyk.io builds observability around structured JSON logs from Node.js/Python services on Kubernetes, using Bunyan, Fluentd and Logz.io (ELK). The team logs one log per request with a carried structured JSON context (keys for user, duration, HTTP status mapped to log level), masks tokens/emails, and skips or samples 200s to control volume. Current telemetry is ~15 GB/day, ~43,000 requests/24h with ~560 >3s and 332 errors in 4h, and dashboards for percentiles and pod-level errors prove the approach works.
AI-written summary · about
chapters (14)
- 0:00Intro
- 2:07Some context
- 3:21My take on observability
- 6:14With proper observability you have
- 7:20How do we get there
- 8:43Logs to the rescue
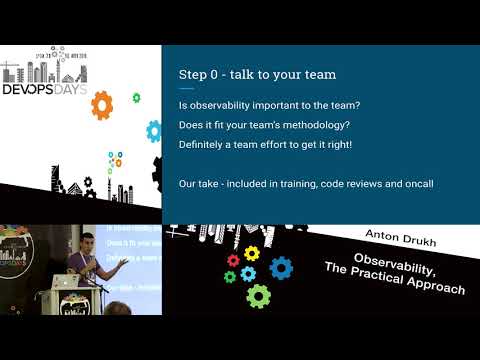
- 9:35talk to your team
- 11:40where to keep your logs
- 13:21start shipping your logs
- 15:12structure your logs
- 21:07protect your logs
- 22:36make logging easy
- 27:41watch out for scale
- 29:59Practical observability
related talks
 12mOpen-source observability is the way forward, and here’s why
 11mKubernetes Observability
 36mObservability? It's a Data Analytics Problem, You Fool!
 24mWhat Observability Can Learn From BI
 39mThe 5W’s of Observability with Practical Examples
 18mNo-Frills Observability For The No-Nonsense...
 32mUnderstanding Observability in Kubernetes
 16mShrinking the Observability Bill