Day 2 Operations of Cloud-Native Systems
summary
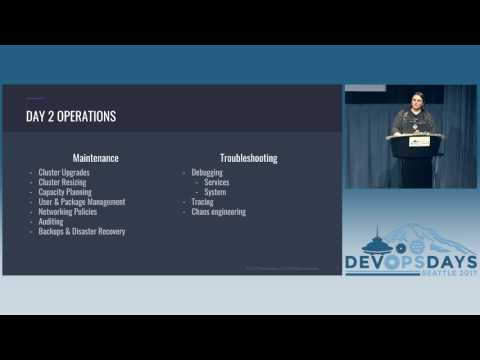
Shows a live Prometheus demo and a backup/restore demo using burry, and argues day‑2 is about concrete tooling not lofty promises. Recommends a consolidated event router (collectd → fluentd → Elasticsearch/Influx) plus unified application ID so traces follow an app through DC/OS/Marathon. Gives a concrete failure example — a resource‑offer rejected for insufficient memory — and reports a chaos run that briefly breaks the cluster. Emphasizes upgrade/cycle policies for stale containers.
AI-written summary · about
chapters (10)
- 0:00Introduction and background
- 2:30The challenge of day 2 ops
- 4:18Managing cloud native layers
- 8:48Metrics and logging strategy
- 14:21Tools for event routing
- 17:58Unified logging and scopes
- 19:01Troubleshooting and tracing
- 20:08Diagnostics and chaos testing
- 23:42Maintenance and best practices
- 28:08Summary and closing
related talks
 31mCloud Native Observability
 25mThe Absolute Beginner's Guide To Cloud Native
 37mBuilding a Day1/Day2 Application Operations Platform On CNCF Projects
 03mCore Project Updates Track Introduction
 36mKubernetes Day 2: Cluster Operations [I]
 01h 29mTutorial: A Day in the Life of a Cloud Native Developer
 42mAn Introduction To Cloud Native Technologies
 47mKubernetes Day 2 to 5