Aligning DeepSeek R1
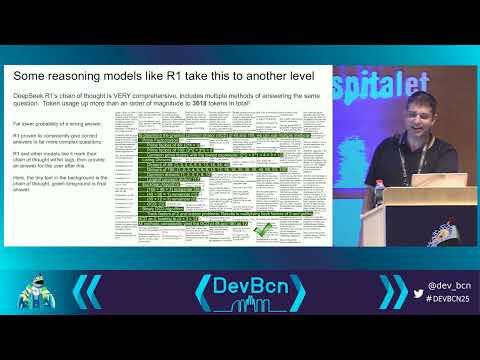
summary
Re‑aligned R1‑distill models using PyTorch and Hugging Face transformers with about 7 million tokens of synthetic data drawn from filtered Q&A repos, training 8B on a single 80GB H100 then scaling to a 70B model on eight 96GB H100s; fine‑tuning set ≈40k prompts, test split 10%, one failed run from a too‑high learning rate then a successful 12‑hour run, total cash out ≈€350, outputs match Llama‑like nuance while keeping R1 chain‑of‑thought.
AI-written summary · about
chapters (16)
- 0:00Introduction to DeepSeek R1
- 1:10LLM training and fine-tuning basics
- 4:44Safety training and guardrails
- 6:51Chain of thought in reasoning models
- 9:16DeepSeek R1’s chain of thought output
- 11:01DeepSeek’s model lineage and variants
- 13:49Motivation for aligning R1 with Llama
- 15:34Fine-tuning risks and unintended effects
- 17:02Our alignment process and data
- 19:11Fine-tuning challenges and adjustments
- 20:15Costs and results of alignment
- 21:41Testing and validation of models
- 23:04Safety risks in unaligned models
- 24:50Open source impact and user choice
- 25:54Model availability and local deployment
- 26:19Q&A session
related talks
 44mApropos DeepSeek
 16mNous Research
 43mHarnessing DeepSeek-R1 and OpenSearch for RAG-Powered Intelligent Info...
 01h 06mScaling personalization with AI
 25mFrontier AI Models: A Review of Past Nine Months
 32mScaling Test-time Inference Compute & Rise of Reasoning Models
 01h 00mDeepSeek-R1 Thoughtology: <Thinking> about LLM Reasoning
 54mThe Future of AI: Building the Most Impactful Technology Together