Tutorial: Implicit Bias I
summary
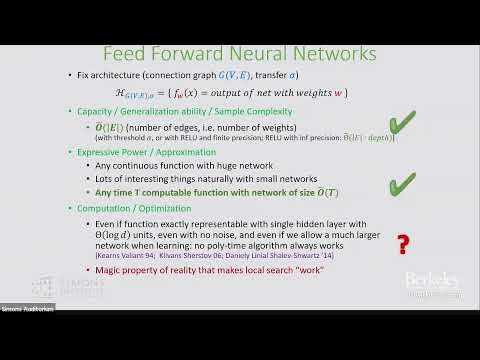
Claims that classic statistical learning tools largely apply to deep learning while implicit bias and benign overfitting need refined views; uses Rademacher complexity, VC dimension and uniform convergence to relate capacity ≈ params×bits and estimation error ≈ sqrt(VC/n). Shows neural nets are universal but often require exponential size, links learnability to computational limits (ERM is NP‑hard, cryptography blocks universal learners), and highlights the practical puzzle that SGD routinely succeeds despite the absence of a proven “magic property” beyond representability.
AI-written summary · about
chapters (10)
- 0:00Introduction
- 5:14supervised learning
- 6:40No free lunch theorem
- 11:32Flat inductive bias
- 22:02Discrete complexity measures
- 26:07Pareto frontier
- 33:58Structures minimization
- 40:48Deep Learning
- 48:45Capacity
- 56:25What can neural networks represent
related talks
 46mOn the Foundations of Deep Learning: SGD, Overparametrization, and Generalization
 01h 03mOverview of Statistical Learning Theory Part 2
 01h 02mTutorial on Deep Learning I
 38mWhy Deep Learning Works: Implicit Self-Regularization in Deep Neural Networks
 50mLearning and Generalization in Over-parametrized Neural Networks, Going Beyond Kernels
 01h 01mOptimization's Untold Gift to Learning: Implicit Regularization
 01h 17mImplicit Regularization I
 01h 04mRandomized Embeddings and Neural Networks