Data Observability and Reliability Engineering in a Real-Time World
summary
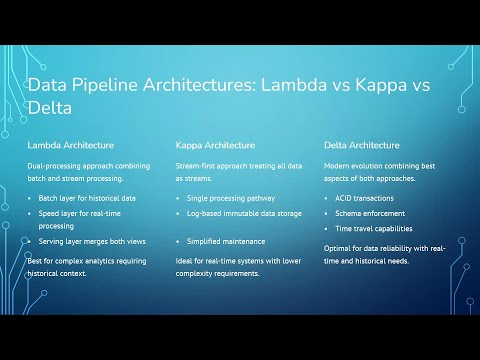
Compares Lambda, Kappa and Delta with concrete tradeoffs: Delta Lake provides ACID and time travel so corrupted rows can be MERGE’d and audited, while replaying three months of streams is costly and error‑prone in Kappa. Lists tools and practices: Hadoop/Spark/Flink, Kafka, Databricks/Snowflake, Iceberg/Hudi, Kafka consumer lag, Flink watermarks, exactly‑once, checkpointing, replication, backpressure, chaos tests and SLOs — and shows medallion bronze→silver→gold flow for reprocessing and governance.
AI-written summary · about
chapters (9)
- 0:00Introduction to data architectures
- 3:33Deep dive into Lambda architecture
- 7:48Kappa architecture explained
- 11:47Delta architecture and Medallion pattern
- 20:02Evolution of data reliability
- 23:29Five pillars of data observability
- 29:12Why data observability matters
- 33:29Reliability engineering principles
- 37:49Summary and closing
related talks
 21mBuilding Data Integration Services In Real Time
 48mAn Evolution of Data Architectures - Lambda, Kappa, Delta, Mesh & Fabric
 38mGetting Started with Delta Lake
 39mDelta Lake: Diving into Data Lakes Without the Downsides
 31mDelta Lake: Open Source Reliability and Quality for Data Lakes
 20mDelta Lake: Turn your Data Lake into a Lakehouse
 22mReliable data engineering made easy
 28mLakehouse Architecture with Delta Lake and Databricks