Delta Lake: Diving into Data Lakes Without the Downsides

Talkat Open AI + Data Forum @ Open Source Summit North America 2022 · on Wednesday, 2022-06-22· at 16:35· Room 408/409 (Level 4), JW Marriott Austin, 110 E 2nd Street Austin, TX 78701·
summary
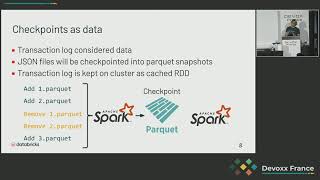
Delta Lake presents an open source file protocol that layers a JSON transaction log on Parquet files to provide ACID tables, with Spark compacting the log into a checkpoint.parquet every 10 commits. It demos concurrent batch writes and streaming reads (an example stream updates Iowa to ~1,800 rows) using optimistic concurrency, supports deletes/updates/merges, offers schema enforcement and time travel versioning, and adds performance tools like Z-order clustering (Hilbert-curve ordering) and an optimize command.
AI-written summary · about
chapters (13)
- 0:00Introduction
- 1:33Modern data architectures
- 5:54Lakehouse architecture
- 6:56Delta Lake internals
- 9:51Concurrency handling
- 14:43Lakehouse features
- 15:46Batch and streaming demo
- 20:01Full DML support
- 24:58Governance features
- 27:47Time travel and versioning
- 31:36Transaction log
- 33:23Performance optimizations
- 37:18Resources
related talks
 20mDelta Lake: Turn your Data Lake into a Lakehouse
 58mBuild reliable data lakes with Delta Lake & Databricks
 31mDelta Lake: Open Source Reliability and Quality for Data Lakes
 38mGetting Started with Delta Lake
 30mDelta Lake and Delta Sharing
 33mThe Pace of Innovation in Delta Lake
 28mLakehouse Architecture with Delta Lake and Databricks
 18mDelta Lake – The Foundation Of Your Lakehouse