Safer Deploys with Test-Driven Infrastructure

summary
Advocates writing monitoring checks before infrastructure and shipping them alongside service code so deployments carry their own health tests. Demonstrations use Goss (one-shot and serve modes) to validate processes, Kubernetes liveness/readiness probes for orchestration, and DataDog’s dog shell to dump a monitor JSON (example: a 200-response monitor, 95% threshold) into git and deploy via Jenkins. Results show deploy-time catches (response dropped from ~30ms to 12ms in a refactor) and SLO/SLI dashboards that enforce error budgets, but continuous runtime coverage needs always-on checks.
AI-written summary · about
chapters (19)
- 0:00Intro
- 0:18Why am I here
- 1:54Ops Experience
- 3:24TestDriven Infrastructure
- 6:58DevOps
- 7:50Infrastructure
- 10:00TestDriven Development
- 16:40Unit Test Configuration Management
- 19:35Functional Testing
- 21:51Troubleshooting
- 22:45Running Tests
- 23:24Defining Response Count
- 23:49Datadog
- 25:01Microservice
- 25:46Jenkins
- 26:38SLOs
- 27:15SLO Monitoring
- 29:02Pilot Perch
- 30:16Why should you care
related talks
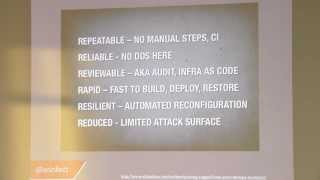 59mDevOps for the Discouraged
 29mObservability Driven Automation: Beyond GitOps with Keptn
 21mYour Deployments Are Lying. AI Knows
 01h 03mTesting in Production
 26mIntelligent Deployment Pipelines
 37m#DataDrivenDevops
 01h 12mPitfalls of Continuous Deployment
 27mHow We Streamlined Our SDLC with Observability - from GitHUB via Jenkins, Harbor, Argo to K8S