Building a Cloud Native Edge Platform for Accelerating AI Inference

summary
A compact, working edge inference stack that runs on a four‑node Jetson cluster using Jetson Mate with 4 Jetson Nano modules, k3s and a shared NFS PVC for model files. Models live as files (Inception GraphDef + labels) and a custom Docker image runs Triton as a DaemonSet (four pods) exposing gRPC/HTTP. Demo sends images (car, cat, tiger, dog), first requests load the model then throughput improves; configuration uses batch size 24 and GPU acceleration.
AI-written summary · about
chapters (10)
- 0:00Introduction to session
- 0:27What is inference at the edge
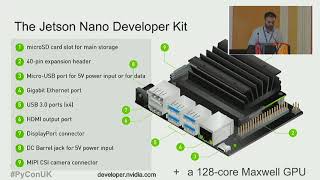
- 2:10Hardware stack with Jetson Nano
- 5:25Nvidia Jetson software stack
- 6:51Triton inference server explained
- 9:00Jetson mate and cluster setup
- 11:51Device overview and demo setup
- 14:44Deploying Triton on Kubernetes
- 22:17Running inference demo
- 25:33Q&A and closing remarks
related talks
 28mMachine Learning on the Edge
 09mDefining Your AI Eco-System with Advantech
 27mModel Serving at the Edge Made Easier
 55mLarge Scale Distributed AI on the JVM
 30mDesigning a Hybrid AI Platform on Kubernetes
 24mInnovation and Solutions for Embedded and Edge AI
 21mA New Architecture for the Intelligent Edge
 51mNvidia Triton Inference Server: building production ML without developers