Optimize your Data Pipeline without Rewriting it

summary
A messy nightly export that takes 24–36 hours becomes measurable and shrinkable: instrumented export jobs, added metrics and dependency triggers, and moved from cron checks and a Luigi bottleneck into evented runs writing directly to Google Cloud Storage and BigQuery. Parallelizing reads across databases and focusing on the critical path cuts end-to-end time from ~36h to ~8–12h, shows which table exports block everything, and proves the fix works in production.
AI-written summary · about
chapters (9)
- 0:00Intro
- 0:53The Phoenix Project
- 2:31Who am I
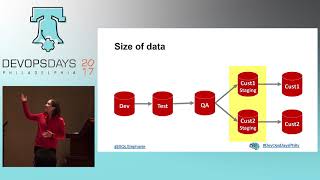
- 11:27Breaking down the data
- 12:50Parallelization
- 14:19Idle times
- 16:59Finding bottlenecks
- 20:58Process
- 22:23Metrics
related talks
 25mData Demons: Unleashing Chaos or Driving Performance?
 16mExploring Query Optimization: How a few lines of code can save hours of time
 30mReliable Data Processing with Minimal Toil
 38mData Secrets from a Platform Engineer
 27mStrategies to Edit Production Data
 31mHelp! My Database Is The Bottleneck
 33mMeasuring DevOps
- 16mExploring Query Optimization: How a few lines of code can save hours of time