Searching through large graphs using Elasticsearch
summary
Project turns a cultural-heritage graph into multiple indices and small flattened JSON fragments stored in MongoDB, transformed with declarative GSLT/JSLT rules, and indexed into Elasticsearch via a Spring Boot search API orchestrated by Talend. Nested documents handle common joins; heavy preprocessing cuts indexing time from weeks to under 48 hours for 50 million documents (≈800 GB index). NeoLoad tests show stable search latencies around 200 ms up to ~400 concurrent users, so the pipeline and API meet the performance targets.
AI-written summary · about
chapters (19)
- 0:00Start
- 1:57National Audiovisual Institute
- 3:26Data Lake Project
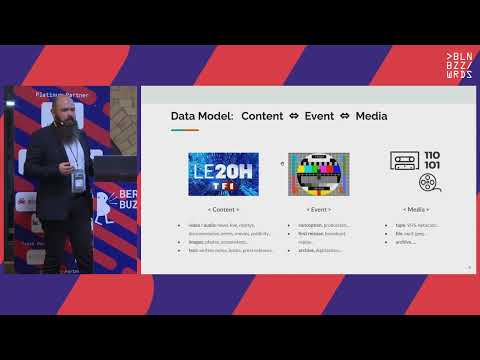
- 4:54Data Model Content Event Media
- 7:14Data Model Content Metadata
- 8:31Data Model: Global schema
- 9:22Data Model Relational database
- 9:54Challenge: Graph transposition into (flat) documents
- 12:03Indexing workflow
- 14:44Data Model representation
- 16:29JSON fragment schema
- 18:02JSON fragment example
- 19:10JSLT transformations
- 22:23Indexing jobs: Talend framework
- 23:23Indexing job example
- 27:52Search example
- 29:25Search workflow
- 30:53Search engine architecture
- 31:54Evaluations
related talks
 45mExploring Large Graphs at the Heart of the French National Audiovisual Ins.
 16mSo many results... Give them to me!
 54mAdvanced (elastic)search for your legacy application
 47mAdvanced (Elastic) Search for Your Legacy Application
 01h 00mAdvanced search for your legacy application
 47mMake sense of your (big) data using Elasticsearch
 36mSearch on the fly: how to lighten your Big Data
 01h 29mSpring Data Neo4J