Logging at scale using Graylog - Billion+ messages, 100K req/sec

summary
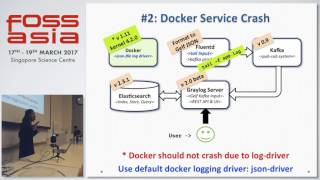
Centralized logging for OlaCabs handles billion+ messages per day at 100K req/sec using Graylog + Kafka + Docker; initial pipeline with fluentd and a GELF plugin is slow and causes Docker daemon crashes from logging-driver buffering, so logs move to file JSON + tailing and Kafka as the durable buffer. Elasticsearch hits a 32 KB field limit so messages truncate to an 8 KB field and all types convert to strings. Heka replaces fluentd and proves Heka is 10x CPU friendly 5x memory friendly.
AI-written summary · about
chapters (12)
- 0:00Start
- 3:02Great UI, best for viewing logs
- 3:23Dashboard
- 4:07Easy manageability of Elasticsearch indexes
- 4:56Several input & output options
- 5:43Real-time log analysis & alerts
- 6:42Initial Pipeline
- 10:08Docker Service Crash
- 11:50Huge lag due to 3 MB log messages
- 13:05Inconsistent schema problem
- 14:49Journal/Buffer utilization too high
- 17:34Questions?
related talks
 31mLogging at Scale, Billion+ messages, 100K msg/sec
 46mBuilding a scalable logging platform
 48mLogging and ranting
 28mFrom Fragmented Logs to Unified Insights: Scaling O11y
 20mFast log management for your apps
 30mBuilding a Large-Scale, Streaming-Based Logging and Monitoring Solution
 39mFast log management for your infrastructure
 33mFluentd and Distributed Logging [I]