Training Large Language Models: Practices and Research Questions
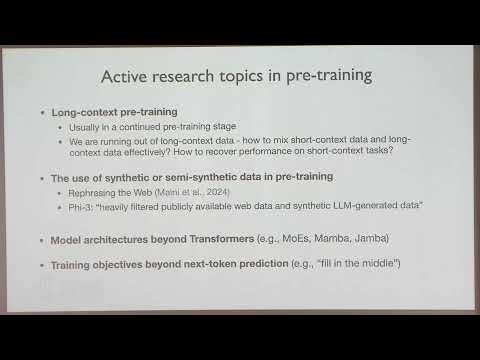
Talkat Special Year on Large Language Models and Transformers, Part 1 Boot Camp · 2024-09-04..09-06·
summary
Comprehensive pipeline coverage focuses on concrete claims, tools and numbers: influence-based selection picks 5% of instruction examples and can outperform training on the full set when selected with gradient features from a 7B model for transfer to 13B; a reference-free preference optimizer called SimPO replaces DPO’s pi_ref with length-normalized log-likelihood plus a margin and shows consistent gains (examples: base SFT → ~22% win rate, off‑the‑shelf instruct ~26% → on‑policy + better reward → ~44.7% then ~53% vs GPT‑4); pretraining notes include Llama‑3’s 400B params on 15.6T tokens and 128k context and growing use of model‑based quality filters (FineWeb, QuRating).
AI-written summary · about
chapters (6)
- 0:00Training LLMs introduction
- 7:27Post-training and fine-tuning
- 28:16Preference learning algorithms
- 58:55Evaluating preference optimization
- 1:14:38Pre-training data curation
- 1:37:47Q&A
related talks
 28mFine-Tuning Small Language Models with Python
 25mTraining Large Language Models in the Open
 43mState of GPT
 23mUnveiling the Journey of NLP
 42mPost-Training Small Language Models: the adventures of a practitioner
 39mCollect Data to Fine-Tune Your Large Language Model
 19mSystem for Scaling Large Language Models
 43mBeyond the Hype: A Realistic Look at Large Language Models