Goku Flow: A Self-Service Data Pipeline Builder
summary
Workday runs about 20 petabytes of operational logs and ingests roughly 2 trillion messages per month; Goku Flow is an in-house, patent-backed self-service pipeline and workflow engine that hides IO and infra details, offers a DSL plus drag‑and‑drop UI, schedules and horizontally runs Spark/Python/R tasks, integrates with Kafka, Spark, Delta data lake and Superset, and automatically publishes versioned tables and email notifications. The demo shows flows completing, tables registered and dashboards auto-refreshing, demonstrating the system works for automated analytics across 740+ service tables.
AI-written summary · about
chapters (16)
- 0:00Start
- 1:51Workday
- 2:29Water Bucket Problem
- 3:49Optimize Cloud Services
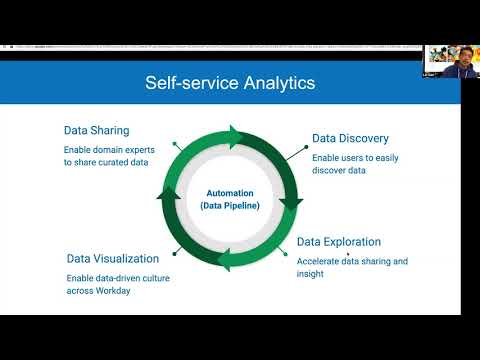
- 5:33Self-service Analytics
- 8:22Big Data Platform
- 9:24Goku Platform (Technology)
- 13:30Goku Flow
- 13:45Solutions
- 14:43Requirements
- 16:47Distributed Data Pipeline
- 18:13DSL Language
- 19:11UI Flow Builder
- 19:32Goku Context (API Abstraction)
- 21:00Data Sharing
- 22:36Demo
related talks
 09mDemo: Deploying Gemma at dataflow scale
 31mA Journey of Migrating Data Platform from Data Center to Cloud
 24mVisual Flow, open-source ETL tool powered by Apache Spark
 28mNo JVM, no Kafka: the future of streaming data pipelines
 17mDatabricks LakeFlow: A Unified, Intelligent Solution for Data Engineering
 26mETL pipeline with GCP Dataflow
 26mGo with the Flow: Automating Your Workflows with Airflow
 48mUsing Open Source Tech to Swap Out Components of Your Data Pipeline