"Data Engineering: The World Between Worlds"
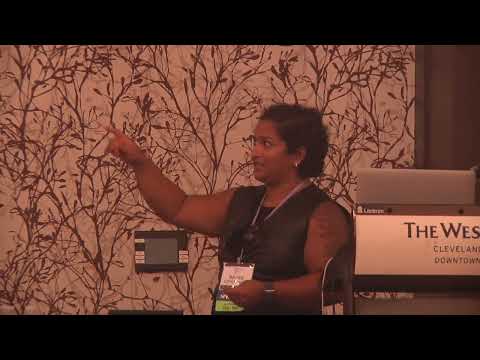
summary
One engineer's 5–6 year journey maps data engineering as the bridge between OLTP and OLAP, owning ingestion, transformation and serving cleaned features for ML instead of the flashy model math. Concrete work includes building an SEO experimentation framework that joins clickstream and third‑party marketing feeds. Pipeline stack and infra examples: PySpark, dbt, Airflow, Terraform, Docker/Kubeflow and vector DBs for model outputs. Core claim: clean, contextualized signal is what makes ML and analytics actually useful.
AI-written summary · about
chapters (10)
- 0:00Introduction
- 3:58Frontend to data engineering
- 8:13Invisible world of data engineering
- 10:00DBAs and data ingestion
- 13:52Self-service analytics tooling
- 17:04Analytics engineers' role
- 19:35Data quality for AI/ML
- 21:42Skills for data engineers
- 22:26Why invest in data engineering
- 24:14Plumber metaphor and conclusion
related talks
 40mData Engineering in a Rapidly Changing World
 24mGotta Feed the Beast - Data Engineering at Scale
 22mDataEngBytes 2023 - BRI-T1-06 - Yanir Seroussi
 57mBACK TO THE FUTURE: EMERGING TRENDS IN DATA ENGINEERING
 51mPanel Debate: Rise Of The Data Engineer
 01h 17mData Engineering in the AI Era: Building a Robust Foundation for AI Applications
 38mThe Rise & Downfall of the Data Engineer REVISITED
 30mData Engineering building your BI infrastructure from scratch