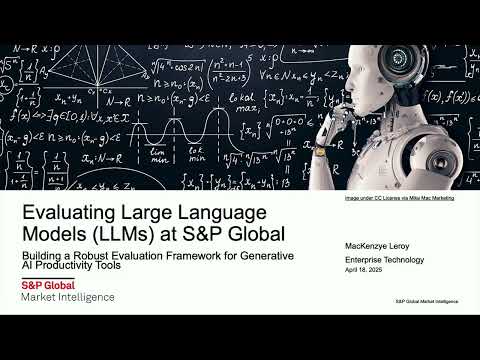
Building a Robust Evaluation Framework for GenAI Productivity Tools
summary
S&P Global describes an enterprise evaluation framework that measures retrieval and generation separately for a RAG tool called MI sales assistant, uses MLflow in SageMaker for daily runs and CloudWatch for metrics, combines LLM-generated and SME-verified ground truth, runs 20–25 stratified samples each day plus comprehensive suites on major changes, cuts onboarding to under two weeks and achieves 70% fewer SME hours, detects document conflicts across teams, and adds automated monitoring, expert validation, and hallucination/security checks.
AI-written summary · about
chapters (11)
- 0:00Introduction
- 1:06MI Sales Assistant tool
- 4:18Evaluating GenAI productivity tools
- 6:46Metrics for retrieval and generation
- 13:25Ground truth data with experts and LLMs
- 16:35Implementation with MLflow and AWS
- 18:23Evaluation framework walkthrough
- 20:07Daily testing and deployment
- 21:30Results and knowledge base improvements
- 22:33Future plans and security
- 23:37Q&A
related talks
 26m7 Habits of Highly Effective Generative AI Evaluations
 08mProduction Evals For Agentic AI Systems
 30mDeveloper Productivity for GenAI Apps
 47mHow to Build Enterprise-Grade AI Agents Using Robust Evaluation
 20mDeveloper Productivity in the Age of GenAI
 40mHow [not] to evaluate your RAG
 15mEnsure AI Agents Work: Evaluation Frameworks for Scaling Success
 29mGenerative-AI: Usecase-Specific Evaluation of LLM-powered Applications