What we learned by converting a large codebase from Pandas to Polars
summary
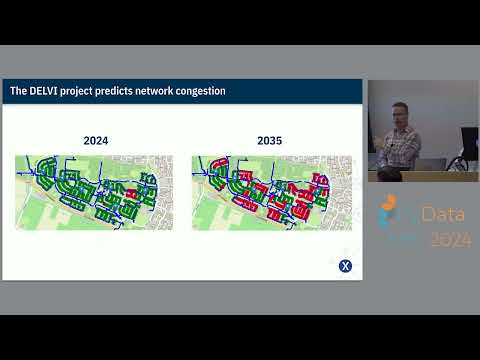
Converted about 20,000 lines from Pandas plus some R to Polars, with concrete benchmarks: isolated hotspots drop from 30s → 1s after switching RDS to parquet and using Polars’ lazy API, peak memory falls roughly 500GB → 40GB (≈92% reduction), and a single network job goes from ~5 hours to ~4 hours. The team reports a stated 98% cost reduction overall and the migration is incremental — benchmark small pieces, use lazy where it helps, collect intermediate results to curb peaks, and measure often.
AI-written summary · about
chapters (17)
- 0:00Pandas to Polars conversion
- 3:19Why Polars is fast today
- 5:30Alliander project challenges
- 8:22Pandas and R bottlenecks
- 10:12Convincing team to try Polars
- 12:24First benchmark results
- 13:06Benchmarking for optimization
- 15:55Lazy evaluation with Polars
- 17:00Balancing lazy and eager modes
- 20:10Polars data types benefits
- 21:35Polars avoids Pandas index issues
- 22:59Polars missing value handling
- 24:25Migration process steps
- 25:29Joining Polars community
- 26:13Final conversion results
- 28:45Key migration lessons
- 29:08Q&A
related talks
 58mFrom Pandas to Polars Upgrading Your Data Workflow
 28mExpressive & fast dataframes in Python with polars
 38mExpressive and fast dataframes in Python with polars
 34mBridging Pandas and Polars
 30mIs the great dataframe showdown finally over? Enter: polars
 25mIntegrating Rust with Python...
 32mHow to do real TDD in data science? A journey from pandas to polars with pelage!
 40mBeyond Pandas: The Great Python Dataframe Showdown