Open Source is Better Together- GPU Python Libraries Unite

summary
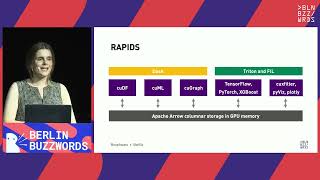
Rapids presents concrete interoperability work: it leverages Dask and UCX to reduce communication stalls, adapts Apache Arrow for columnar exchange, and implements CUDA array interface and DLPack bridges so tensors move without copies. The ecosystem faces 14 competing backends — 14 device array implementations — so efforts focus on lightweight adapters and standard dispatch. A GPU forest inference engine already runs XGBoost models with about a 30× speedup for XGBoost inference, with scikit‑learn and cuML support planned.
AI-written summary · about
chapters (14)
- 0:00Open-source GPU Python libraries
- 1:15Python in data science & ML
- 3:42Python: simplicity vs performance
- 6:32GPUs for Python scalability
- 9:21Apache Arrow in Python
- 12:58RAPIDS ecosystem & deep learning
- 14:46RAPIDS: Cython & Dask
- 18:43OpenUCX for multi-GPU performance
- 22:37Unifying GPU Python libraries
- 25:47NumPy array function standard
- 31:22CUDA array interface
- 35:59DL Pack & tensor interop
- 38:27GPU library interop summary
- 39:07Q&A on dependencies & challenges
related talks
 01h 08mGPU Data Science with Rapids
 20mEnd-to-End Data Science on GPUs
 55mAccelerated Python: The Community and Ecosystem
 39mAccelerating Data Science with RAPIDS
 41mLuxuries, necessities, and the challenges that remain
 02h 55mGPU Accelerated Python w: CUDA
 01h 22mHigh-Performance Data Science at Scale with RAPIDS, Dask, and GPUs
 41mAccelerating Data Science with RAPIDS