Bulk Labelling Techniques
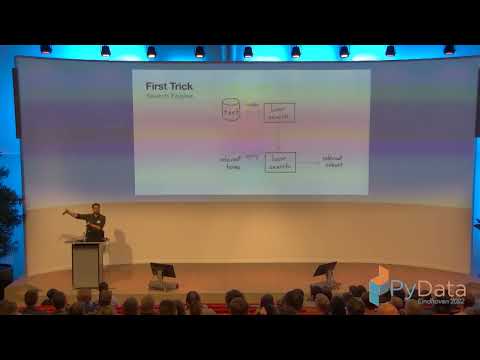
summary
Claim: few‑shot embedding selection reaches ~74% accuracy with four seed sentences using KNN while a bag‑of‑words model needs about 500 labeled examples to match it. Practical tools mentioned: lunr.py, sentimany, embetter, umap, spaCy, sense2vec, Prodigy, pigeon and scikit‑learn. Two packages get built: embetter (scikit‑learn embedding pipeline) and bulk (2D UMAP cluster selector exporting CSVs). Freezing a backbone and training a tiny task head on ~20 cat/dog labels produces clear cluster separation; demo works locally but not on the big screen.
AI-written summary · about
chapters (10)
- 0:00The importance of data
- 1:32Data pipeline problems
- 4:43Manual annotation tools
- 7:34Bulk labeling strategies
- 11:01Using text embeddings
- 15:53The embetter library
- 19:21Embedding trick results
- 20:45Visualizing data with bulk
- 23:27Active learning approach
- 27:08Conclusion and Q&A
related talks
 39mMaking Use of All Your Data, Labelled or Otherwise
 01h 26mBagging to BERT- A tour of applied NLP
 43mADAM - Bootstrapping a Deep Neural Network Sequence Labeling Model with minimal labelling
 51mEfficient Deep Learning with Humans in the Loop
 41mBetter Machine Learning with Less Data
 37mOptimal on Paper, Broken in Reality
 20mPragmatic Deep Learning for image labelling
 30mStarting deep learning projects without enough labelled data