Bridge to the Cloud

summary
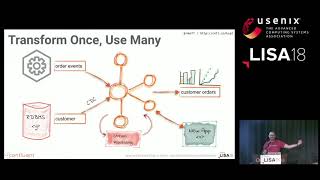
Overview of a working pipeline: a local Java producer loads 20 customers and streams orders at ~50 events/sec into Apache Kafka, a running Confluent Cloud cluster on AWS via the replicator connector which handles topic rename, offset translation and provenance headers. ksql performs a real-time join and per-customer aggregation; data can sink to Redshift or Lambda. Service advertises a 99.95% SLA; demo shows end-to-end replication and stream processing successfully operating across the single opened network pipe.
AI-written summary · about
chapters (10)
- 0:00Introduction
- 1:10Survey results
- 2:33Risk
- 3:09Kafka
- 6:39Kafka Summary
- 10:19Cloud Integration
- 12:16Demo
- 17:13Replicator
- 21:02Connectors
- 21:46Code
related talks
 39mUsing Streaming Data Pipelines in the Cloud to Achieve Success
 40mA Data Mesh Of Streams
 26mConnecting distributed data with Apache Kafka
 53mApache Kafka and KSQL in Action : Lets Build a Streaming Data Pipeline!
 39mData Streaming? I don't even know her
 43mApache Kafka and KSQL in Action: Let’s Build a Streaming Data Pipeline!
 03h 00mStream Processing, Going Beyond Pub/Sub with Kafka Streams and...
 26mLeveraging Data in Motion in a Cloud-first World