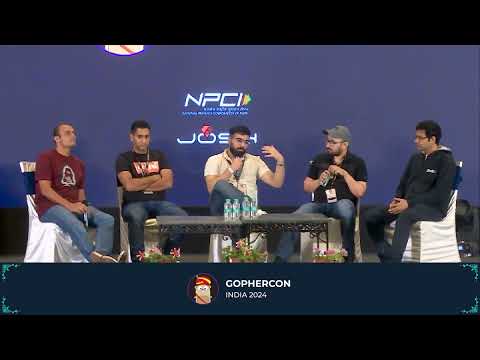
Panel Discussion - Performance & Scalability
summary
500 TB moves from AWS S3 to GCS in 2.5 days using a custom Go pipeline that reads metadata from Bigtable, spawns worker nodes to fetch S3 objects, validates MD5/ETag, and retries failures; a practical lesson shows 500 TB in 2.5 days, Go routines + channels and a surprising channel slowdown past ~60 cores. Notes on rate limits (hit cloud quotas and a near-$1M bill), storage swaps (ClickHouse cuts imports 4h→15m, Pebble DB replaces Redis), and pod tuning (avoid CPU limits, match requests/limits).
AI-written summary · about
chapters (16)
- 0:00Introduction to Scaling and Performance
- 0:41Meet the Panelists
- 3:35Prerath's Data Migration Journey
- 5:36Challenges and Solutions in Data Migration
- 8:30Concurrency and Scalability Insights
- 16:56Storage Solutions and Performance
- 25:14Building a High-Performance Team
- 27:58Benchmarking and Bandwidth Analysis
- 28:30Pair Programming Models
- 28:54Building a High-Performance Team
- 29:35Remote Work Challenges
- 31:15Audience Experiences with Team Management
- 35:26Optimizing Kubernetes Pods
- 41:07Debate: Quality vs. Speed
- 48:42Microservices and Team Structure
- 52:19Final Thoughts and Takeaways
related talks
 12mSometimes you need to be a cruise director
 51mScaling Sustainable Innovation through Team Autonomy
 25mLessons From Running Ceph as a Platform at Scale
 30mBuilding Stable, Scalable & Agile Distributed Systems at Enterprise Scale
 50mScaling for Global Growth with Modern Cloud
 52mFrom 0 $100 billion: Inside lessons on how to scale your dev workflow
 48mScaling for Global Growth with Modern Cloud
 24mHow to design your team for scale