Open models and open compression
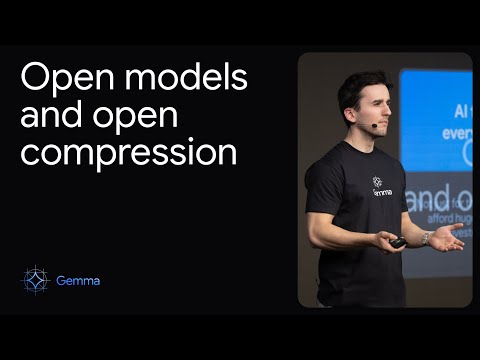
summary
Claims that Gemma runs compressed without quality loss, showing Q4_0 (≈4.5 bits per weight, one scale per 32 values) and an FP8 variant about 2× smaller than bfloat16, and that a 12B model with 30k context runs on consumer GPUs/TPUs/unified memory. Implementation uses quantization-aware training via self-distillation with a frozen teacher and a quantized student, released in Flax and available on gemma.ccp/Hugging Face; a mobile demo solves riddles offline in <1s and fine-tuning works on one GPU.
AI-written summary · about
related talks
 16mGemma 4: Compacting Intelligence for the Edge
 10mDemo: Using Gemma with the Hugging Face ecosystem
 15mGemma, DeepMind's Family of Open Models
 16mOpen models in the Gemini era
 39mFlutter Project with Gemma: A State-of-the-Art Open Model
 19mGemma 4 Deep Dive
 08mDemo: JAX, Flax and Gemma
 43mRunning open large language models in production with Ollama and serverless GPUs