Flink's application at Didi
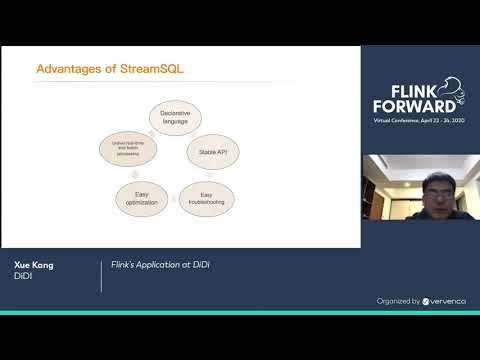
summary
Built a Flink-based real-time platform and a SQL layer that lets non-experts write streaming jobs; StreamSQL based on Flink Table API runs alongside custom schedulers and resource-tuning that adapt configs from observed CPU and memory use. Platform serves hundreds of teams with 1000+ Hadoop nodes and ~3000 Flink jobs (about 2000+ SQL jobs) processing 2 trillion records per day, with Kafka sources and sinks to HDFS, HBase, Elasticsearch and ClickHouse; challenges are large state IO, HA recovery and multi-language support.
AI-written summary · about
chapters (15)
- 0:00Intro
- 0:27Guideline
- 0:59History of stream computing at DIDI
- 3:38Business Scenarios
- 6:13Multi-Cluster Architecture
- 8:30Advantages of StreamSQL
- 10:02Refined DOL
- 12:14UDX Extension
- 13:26Stream Join
- 15:04StreamSQL DE
- 15:46Job Management
- 16:44Job Operations
- 17:55Stream Meta Construction
- 19:31Challenges
- 20:37Future Plan
related talks
 43mLeverage the power and simplicity of SQL on Apache Flink
 47mBring Flink to Large Scale Production
 39mBetter, Faster, Stronger Streaming: Your First Dive into Flink SQL
 23mBetter, Faster, Stronger Streaming: Your First Dive into Flink SQL
 41mBeyond the Hype: When Apache Flink Solves Real Problems
 32mThe easy way to build and run Flink SQL jobs using Cloudera SQL Stream Builder
 35mApache Flink 2.0: Unified Enterprise Data Processing System and Beyond
 37mKeynote | Flink Ahead: What Comes After Unified Batch & Streaming?