The Future of Data in Ember
summary
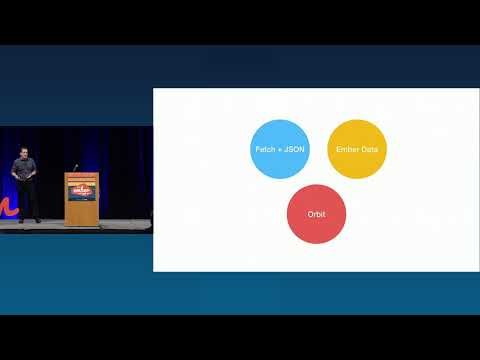
Builds a small app three ways and shows what each actually buys: plain fetch + service workers for offline caching; Ember Data for CRUD with adapters/serializers as it becomes faster, lighter-weight, and more modular; and Orbit via ember-orbit to queue failed requests, persist to IndexedDB, fork and merge stores, and retry until synced. Notes JSON:API’s move toward operations, cites 50+ server and 50+ client libraries, and demonstrates which upgrades required big rewrites and which can be incrementally adopted.
AI-written summary · about
chapters (11)
- 0:00Start
- 24:53new interfaces unlock experimentation
- 28:17data access and synchronization
- 35:39how does orbit fit with ember data?
- 36:47ember data can provide orbit's capabilites in a convention-driven package
- 37:23orbit and its ecosystem can provide a laboratory for experimentation
- 39:08The operations primitive will be adopted across the stack.
- 39:21Static analysis will improve runtime efficiency
- 39:35Immutable data structures will see increased internal usage.
- 41:56Config
- 44:00let's build great things together!