Building Tecton’s Feature Engineering Platform on DuckDB
summary
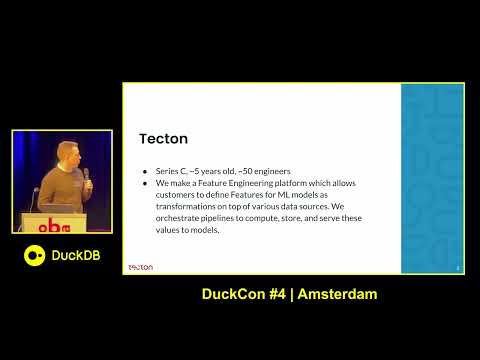
Tecton replaces Spark with DuckDB and Arrow-based pipelines to compute feature values, store them in Delta Lake, and export training sets; jobs for many customers now finish faster than Spark cluster startup and the system scales comfortably to tens of gigabytes (private preview with 5–10 customers). Implementation uses Arrow I/O, pandas UDFs, and DuckDB for aggregations and joins; engineers build a custom DuckDB extension for missing aggregations, wrestle with Delta Lake integration and AWS credentialing on laptops, and report much simpler demos and deployments.
AI-written summary · about
chapters (5)
- 0:00Introduction to Tecton
- 1:37Challenges with Apache Spark
- 2:26Building with DuckDB and Arrow
- 3:36Performance and early results
- 4:41Implementation challenges
related talks
 27mThe Duck and the DataFrame: A Data Engineer’s Journey with DuckDB
 28mAnalyze data easily with duckdb - and the implications on data architectures
 10mUsing DuckDBArrowFlight to Power a Feature Store
 40mDuckDB beyond the notebook
 34mData Wrangling with DuckDB
 40mDuckDB: Harnessing in-process analytics for data science and beyond
 40mDuckDB Meets Data Lakes
 25mA quack of all trades: DuckDB, a versatile analytical database to keep in your toolkit